Which recipe comments should you read for feedback?
Reading the most-upvoted or newest comments can change the rating mix you see. A ten-comment comparison across 100 selected recipe discussions shows why the reading method should follow the question you want to answer.
An analysis of 18,182 comments in a recipe archive released by UCI in 2023.
Abstract
When the aim was to reflect a recipe discussion’s rating mix, random selection was closer on average than choosing the most-upvoted or newest comments. Influence IQ compared ten-comment selections across a selected set of 100 highly rated recipes in a historical archive of 18,182 comments released by UCI in 2023. Mean expected rating-mix gaps were 16.5 percentage points for random selection, 18.7 for upvotes and 20.3 for newest comments. [1][4]
The result measures the mix of one-to-five-star and unrated comments, not the usefulness of their advice. Upvote selection was closer than random selection for 46 recipes and farther away for 54. For food creators and community managers, the implication is to distinguish a sample used to summarize a discussion from examples used to plan a response.
You have a recipe to improve and a long discussion underneath it. There is time to read a small set of comments before deciding what to clarify. Do you start with the comments that attracted the most votes, the newest arrivals or a random selection from the discussion?
That choice happens before you interpret a single sentence. It determines which voices enter the brief you hand to a creator, editor or colleague. We examined how three explicit selection rules changed one measurable feature of that brief: the balance of ratings, including comments whose authors left no rating.
A selected view of a larger discussion
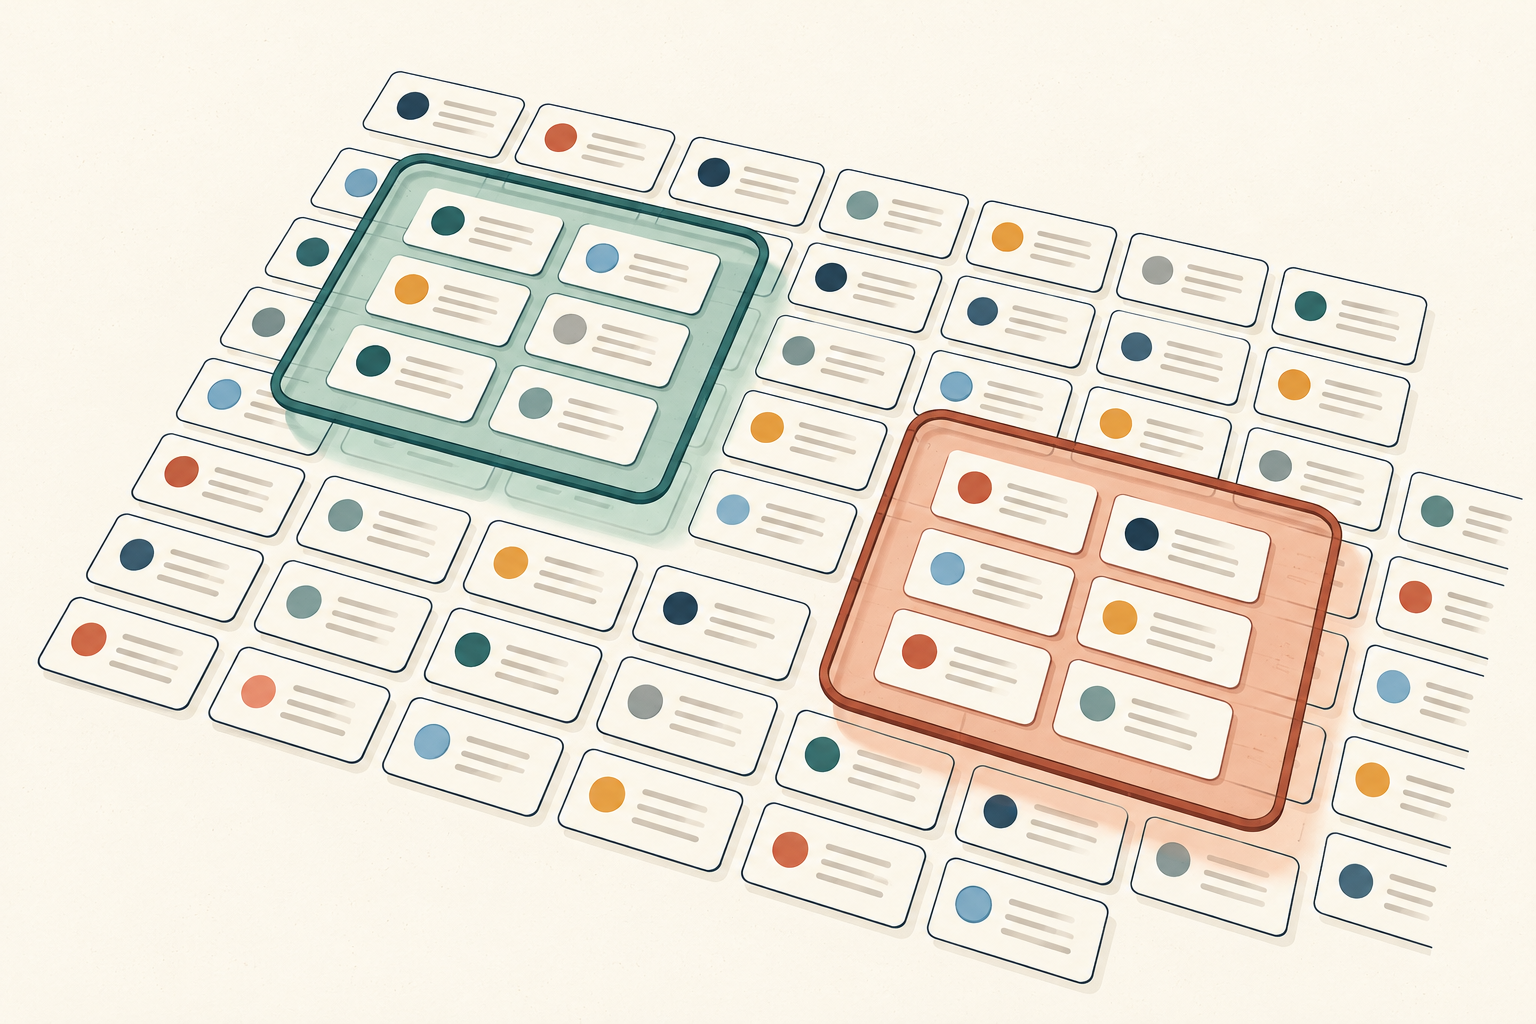
- Selected comments
- Full archived discussion
Ten comments can give three different views
A recipe creator preparing a follow-up needs to decide what to read first. The most-upvoted comments may look like a useful shortcut. The newest comments offer another route into the discussion. Both put some comments ahead of others, but neither selection automatically describes the whole discussion.
We tested that narrow question using 18,182 archived comments on 100 selected, highly rated Taste of Home recipes in a public dataset released through UCI in 2023. For each recipe, we compared ten comments chosen by upvotes, ten chosen by creation time and ten chosen at random. The reference was the rating mix of all archived comments on that recipe. [1]
The average expected gap from the full rating mix was 18.7 percentage points for the upvote selection, 20.3 for the newest selection and 16.5 for random selection. Each recipe contributed equally to those averages, regardless of how many comments it had. [4]
Compared with random selection, the gap was 2.2 percentage points larger for upvotes and 3.8 points larger for newest comments. These differences concern the mix of ratings and unrated comments. We did not measure which comments offered the best cooking advice, the clearest explanation or the most useful business idea.
That distinction matters for a food creator or community manager. A comment can be valuable enough to inspire a tutorial without being typical of the discussion. Treating it as an example is a different decision from treating a shortlist as a summary.
Average gap from each recipe’s full rating mix
Ten comments per selection, across 100 selected recipe discussions in the historical UCI archive. A smaller gap means a closer rating/no-rating composition match.
| Selection method | Mean expected gap |
|---|---|
| Most-upvoted | 18.7 percentage points |
| Newest by creation time | 20.3 percentage points |
| Random selection | 16.5 percentage points |
What does a rating-mix gap mean?
Think of each recipe discussion as a mixture of six categories: one through five stars, plus comments with no rating. A ten-comment sample has its own mixture. We measured how far that smaller mixture was from the full archived discussion, using a measure called total variation distance.
Here is a hypothetical example with only two categories. Suppose half the comments give four stars and half give five stars. If a ten-comment selection contains seven four-star comments and three five-star comments, its mix is 70% versus 30%, rather than 50% versus 50%. The distance is 20 percentage points: half of the two absolute 20-point differences.
The same calculation works across all six categories. A smaller value means a closer match to the archive’s rating composition. It does not mean the writing is more informative, or that the comments are more truthful. Nor does an 18.7-point result mean 18.7% of the comments are wrong.
We kept unrated comments in the comparison. UCI defines a zero in the rating field as no rating, not a score below one star. Removing those comments would change the discussion being summarized. The numerical category alone cannot tell us whether an unrated comment contains a question, praise, a problem or something else. [1]
Random selection was closer on average, not for every recipe
The overall comparison does not produce a universal winner. Upvote selection had a smaller expected gap than random selection for 46 of the 100 recipes, and a larger gap for 54. Newest selection was closer for 42 recipes and farther away for 58. Neither comparison had an exact tie. [4]
These are comparisons between each method’s expected gap within a recipe. They do not mean that every possible random draw beats the upvote selection in those 54 discussions. A particular draw of ten comments can happen to resemble the full discussion closely or miss parts of it.
The random result averages over every possible ten-comment sample, with each sample equally likely. It is not the result of one lucky draw or a chosen random seed. We also averaged over possible tie-breaking selections when several comments shared the cutoff upvote count or timestamp.
Cutoff ties required averaging for 70 recipes under upvote selection and four under newest selection. We did not prefer one tied comment because of its author, row position or identifier. The calculation asks what happens under a stated selection rule, rather than treating an arbitrary ordering as evidence. [4]
For a creator, the practical implication is modest but useful: upvotes and recency are selection criteria. If you use either to summarize a discussion, name that choice. Do not assume that a visible shortlist preserves the balance of the whole archive.
The closer method varied across recipe discussions
Each ranked selection is compared with random selection within the same recipe. These are comparisons of expected gaps, not outcomes from individual random draws.
| Selection method | Closer than random | Equal to random | Farther than random |
|---|---|---|---|
| Most-upvoted versus random | 46 | 0 | 54 |
| Newest versus random | 42 | 0 | 58 |
Choose the question before choosing the comments
Customer feedback methods serve different jobs. A business may want to understand a broad pattern, investigate a specific problem or find a question for its next post. This study addresses one part of that work: whether a small selection preserves a discussion’s rating composition. It does not rank all ways of collecting feedback.
If your question is “What does this discussion look like overall?”, begin by defining which comments belong in the discussion. A random selection from an accessible, complete list avoids deliberately favoring votes or recent creation times. In this archive it was closer on average, but a small random sample still had a measurable gap. Ten was our chosen comparison budget, not a recommendation that ten comments are enough.
If your question is “What should I answer next?”, a specific comment may deserve attention on its own. A clear question about an ingredient substitution can justify checking the recipe and preparing an explanation. You do not need to call the question common before responding to it. Its relevance to the next piece of content is a separate judgment.
If your question concerns recent changes, creation time can define a relevant reading window. Keep that window visible in the summary. Newest comments in our study meant the latest creation timestamps in the saved archive, not comments arriving today or the order currently shown on the website.
Even the full comment archive is a limited reference. It contains contributions from people who chose to comment, rather than everyone who read or tried a recipe. If a business needs feedback from people who never comment, it needs a separate way to reach them. A closer match to the comment archive cannot fill that gap. Keep such additional feedback distinct so its source and selection remain understandable.
Keep two separate notes: one describes the selection used to summarize the discussion; the other lists questions worth investigating. This is a suggested planning approach, not a workflow tested in this study.
A fictional example: planning a recipe follow-up
Imagine a food creator planning a follow-up to a baking recipe. A highly upvoted comment asks whether a different pan will work. The creator is tempted to open the next video with “Everyone is struggling with the pan size.” This is a fictional scenario, not a comment or recipe selected from the dataset.
The pan question can be worth answering without showing how common it is. Upvotes do not establish who tried the recipe or shared the same experience.
A more precise brief would say: “A reader asked how pan choice affects this recipe. Show the pan used, explain the dimensions and identify what would need checking before recommending another.” The creator can then verify the cooking details. The comment provides the starting question; it does not establish the answer.
If the creator also wants to summarize the discussion, they should keep a separate note explaining what they read and how they chose it. A random sample from a complete available list should give each comment an equal chance without selecting the same comment twice. Scrolling to a few convenient places is not the random procedure evaluated here.
When a complete list is unavailable, describe the selection you can actually make. “We reviewed the first comments shown under this sort order” is more informative than calling it a representative sample. Do not attach our archive’s numerical gaps to that different process.
The follow-up should show the equipment and answer the checked question. Keep a record of what you clarified so the next review can focus on unanswered questions. Judge that explanation using feedback on the follow-up itself.
Keep selection and interpretation separate
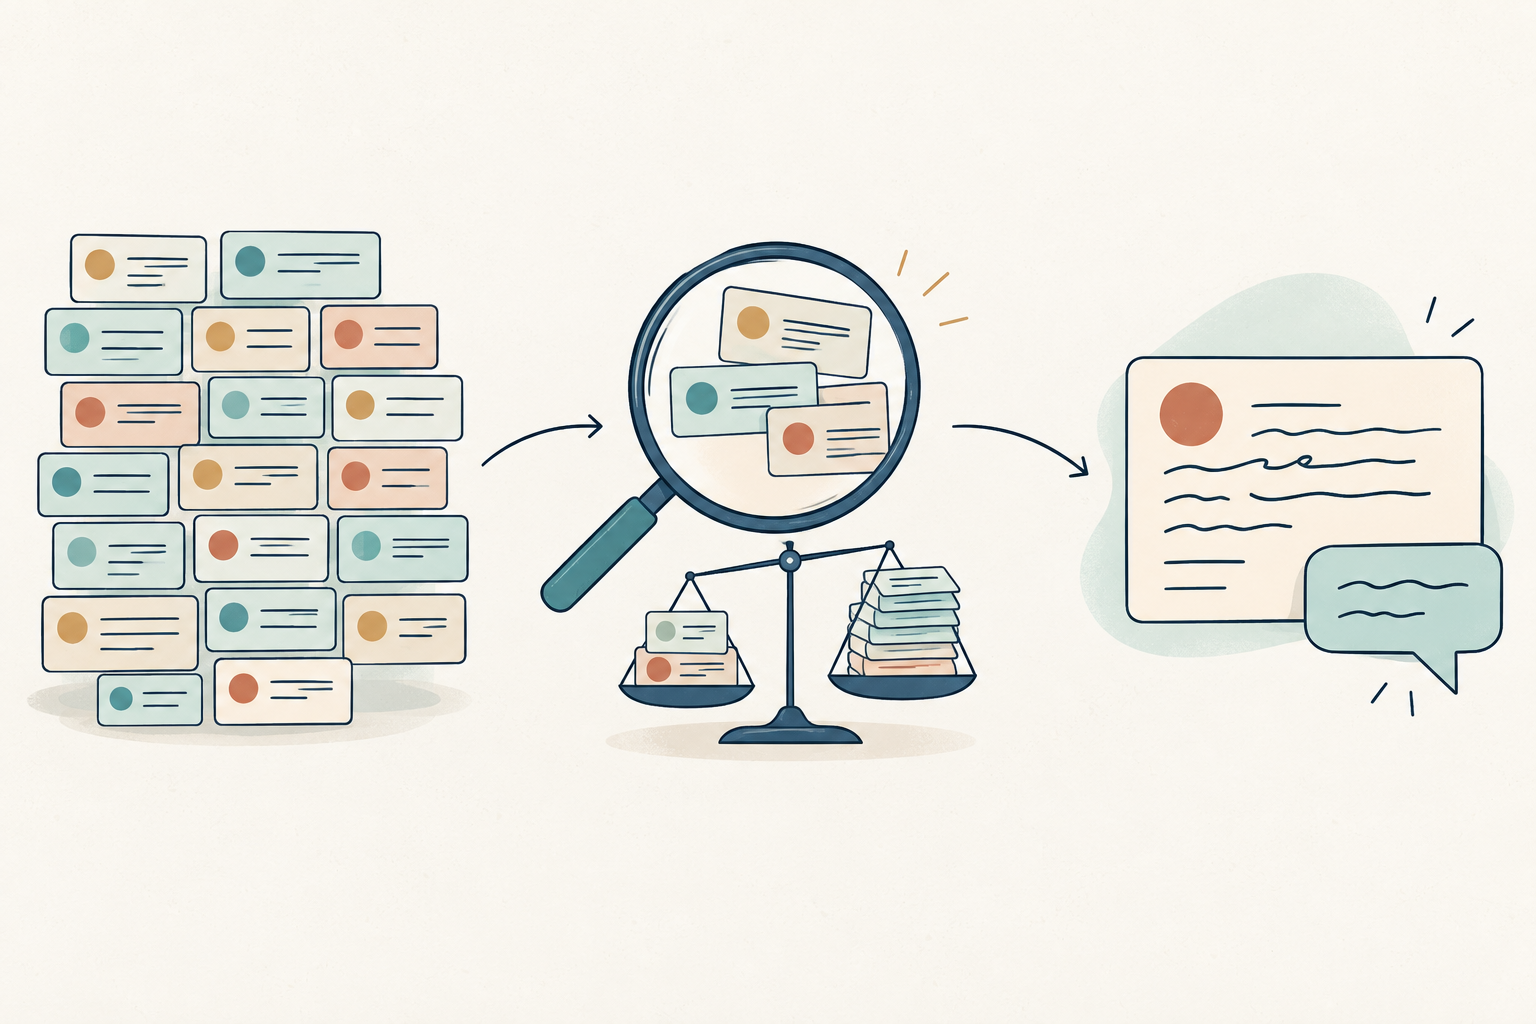
Define the reading set
Name the discussion and the selection rule before reading.
Consider what the selection covers
Keep the selected view distinct from the full discussion.
Read the comment in context
Use the actual question to plan a response and check the answer.
A short brief for reading a recipe discussion
Use these prompts before assigning a creator or colleague to review comments. They are a practical planning aid, not questions from the source dataset.
Decision: What will the reading inform? Name a concrete task, such as clarifying a recipe step or choosing a follow-up topic. Separate a request for examples from a request to describe the whole discussion.
Scope: Which recipe, platform and period are included? State whether the available list is complete. Count comments as comments; do not label them unique people or verified customers without separate evidence.
Selection: How will comments enter the reading set? Record the sort order or random procedure, the number read and any tie rule. Keep comments without ratings in scope when they are part of the discussion you want to understand.
Observations: What did the selected comments actually say? Separate a direct question from your interpretation of it. Retain enough context to understand the issue, while keeping personal information out of a shared brief.
Next action: Which claim or recipe detail needs checking before publication? Assign that check to someone who can answer it. Write the proposed explanation and destination, without turning the selected examples into an unsupported prevalence claim.
How we compared the three selection methods
The source is Ali, Matuszewski and Czupyt’s Recipe Reviews and User Feedback dataset, published by UCI in 2023 under CC BY 4.0. It contains comments from a selected list of 100 highly rated Taste of Home recipes. The release year does not establish an exact collection date, and the available source material does not establish that every original comment was captured. This is a historical archive analysis, not a current platform benchmark. [1][2][3]
We validated the complete released archive: 18,182 distinct comment identifiers across 100 recipe positions. Every recipe had more than ten comments, so all 100 entered the comparison. Repeated commenters remain multiple comments. We did not deduplicate by person or analyze review text, names, user reputation or the source’s ranking score.
For each recipe, the upvote rule selected the ten comments with the highest observed upvote counts. The newest rule used the ten latest creation timestamps. Where the cutoff was tied, every possible way of filling the remaining places from that tie was equally likely. Random selection gave every ten-comment subset of the recipe’s archive equal probability.
For each possible selection, we compared its six-category rating distribution with the full recipe archive, then averaged the distance under the selection rule. Exact probability calculations produce that expectation without simulation. Averaging the distances is important: calculating a distance only after averaging category shares would answer a different question and could conceal sampling variation.
We then averaged the recipe-specific expected distances with equal weight for each recipe. Differences were calculated before rounding to one decimal place. The ten-comment budget, eligibility rules, comparisons and reporting plan were fixed before examining the target results. No alternative budget or favorable subset of recipes was chosen afterward.
The results describe this finite archive and the specified selection rules, so we report no population confidence interval or causal effect. Cumulative upvotes do not reveal exposure or voting history. The original producer paper studies text classification; this analysis instead follows UCI’s documented star categories and examines selection. The technical method explains the source-field distinction. [1][2]
The downloads provide the aggregate results, a numerical audit for every recipe position and reproduction code. They contain no comment text, names or user identifiers. Source records are available separately from UCI; attribution to the dataset authors and repository does not imply endorsement of our interpretation. [1][3]
- Download the English aggregate results (CSV)
- Download the method and reproduction code (ZIP, English)
No sign-up required. Downloads contain aggregate comparisons, numerical results by recipe position and the English technical method. No comment text, user names or individual comment identifiers are included. The source dataset is available separately from UCI. [1]
Sources and notes
- Ali, A., Matuszewski, S., and Czupyt, J. (2023). Recipe Reviews and User Feedback [Dataset]. UCI Machine Learning Repository. DOI: 10.24432/C5FG95. UCI documents 18,182 comments and defines stars 1–5, with 0 meaning no rating. Influence IQ calculations use the released archive, not current website data.
- The producer paper, “Textual Taste Buds: A Profound Exploration of Emotion Identification in Food Recipes through BERT and AttBiRNN Models,” describes the selected recipe source and a text-classification study. Its description of best_score conflicts with UCI’s documented rating field. We use stars and do not analyze best_score or review text. The available material does not establish exact snapshot timing or complete collection coverage.
- The UCI dataset is licensed under Creative Commons Attribution 4.0. Influence IQ has calculated new aggregate comparisons from it. Dataset attribution does not imply endorsement by the authors, UCI or Taste of Home. The downloads do not redistribute individual comments or user identities.
- Influence IQ (2026). Recipe feedback sampling: analysis method, aggregate results and reproduction code. The package records the fixed ten-comment comparison, exact expected total variation calculations, tie handling and numerical results for all 100 recipe positions. The source data are obtained separately from UCI. Technical files are in English.
The article, planning brief, figure labels and results CSV are available in ten languages. The technical reproduction package is in English. Every edition describes the same historical recipe archive and analysis.