Two moderation labels can come from different reviewers
A comment-review handoff can show two labels without showing who chose them. Historical Wikipedia judgments reveal why that missing detail matters for the next person reading the case.
Original Influence IQ analysis of selected judgments in the historical Wikipedia Detox personal-attacks dataset. Analysis completed October 25, 2026 (UTC).
Abstract
Among 13,824 selected historical Wikipedia discussion excerpts, 155 received both a quotation/reporting label & a recipient-directed attack label somewhere in their 10 individual judgments. In 98 of those 155 excerpts, at least one reviewer selected both labels. In the other 57, or 36.8%, the labels came only from different reviewers. The percentage describes those 155 excerpts, not all 13,824.[1][4]
For businesses & creators managing social media comments, the practical lesson concerns the handoff: keep each reviewer’s observations attached to that person’s assessment. Two labels appearing together do not establish that one person chose both. The study describes subjective judgments on historical discussion excerpts, not moderation errors or a rule for removing a comment. A copyable worksheet below turns the distinction into a practical review record.
Imagine a creator asking a colleague to look at a difficult comment. The handoff carries two labels: someone is quoting or reporting an attack, & someone is directing an attack at the recipient. Before deciding what to do, the colleague needs one more detail: did the same reviewer make both observations?
That is a real distinction a summary can lose. One person may have selected both options, or two people may have focused on different aspects of the same text. A list of labels alone cannot tell the next reviewer which pattern occurred. It can also leave unclear which words each person was describing.
We explored that question using individual judgments from an established research dataset. The original material came from Wikipedia discussion pages. Its role here is to make the relationship between labels & reviewers visible, then help a business or creator think through the information to preserve in their own handoff.
Keep each observation connected to its reviewer
Start with what each label actually describes
The first option asked whether the text quoted or reported a personal attack originating in another comment. The second concerned a personal attack directed at the recipient. Reviewers could select more than one option. These were judgments about the presented text, rather than decisions to hide it or evidence that a policy had been broken.[2]
We treated a label as present when at least one of the 10 reviewers selected it. This was an any-reviewer comparison. We did not require a majority, describe the labels as consensus or test whether they were correct.
Of the 13,824 selected excerpts, 12,025 had neither of these two labels. Another 406 had a quotation/reporting label without a recipient-directed label, while 1,238 had a recipient-directed label without a quotation/reporting label. That left 155 with both labels somewhere in their judgments.
Those descriptions concern these two options only. An excerpt without a recipient-directed label could still have another kind of attack label. A quotation/reporting label does not certify that the text was harmless. Keeping the names precise prevents a useful category from quietly becoming a broader conclusion.
How the 13,824 selected excerpts were labeled
A label was present if at least one of the 10 reviewers selected it. These five categories concern two specific options; “neither” does not mean the excerpt lacked every kind of attack label.
| Quotation/reporting & recipient-directed labels | Excerpts |
|---|---|
| Neither of these two labels | 12,025 |
| Quotation/reporting without recipient-directed | 406 |
| Recipient-directed without quotation/reporting | 1,238 |
| Both labels, with at least one same-reviewer pair | 98 |
| Both labels, supplied only by different reviewers | 57 |
57 excerpts had both labels, but no reviewer chose both
Within the 155 excerpts, we checked the individual response behind each label. In 98, at least one person selected both options for that same excerpt. In 57, the quotation/reporting & recipient-directed selections came only from different people. No individual response in those 57 contained the pair.
The split was 63.2% with a same-reviewer pair & 36.8% with the labels supplied only by different reviewers. Both groups belonged to the same narrowly defined set of 155 excerpts. The larger 13,824-excerpt frame remains important because it shows where that conditional comparison began.[4]
The distinction changes the claim you can make from a summary. Knowing that both labels appeared supports saying that each was selected somewhere in the review set. It does not, by itself, support saying that an individual reviewer described the text in both ways.
Nor does the same-reviewer pattern settle what the words meant. A source excerpt could combine additions made during one Wikipedia revision, including more than one post. One reviewer selecting both options does not show that the quoted passage itself was the recipient-directed attack. We did not inspect individual excerpts to explain their judgments.[2][6]
57 of the 155 excerpts had no same-reviewer pair
This comparison includes only the 155 selected excerpts with both labels somewhere across their 10 judgments. It uses any-reviewer selections, not majority agreement or verified moderation outcomes.
| Who supplied the two labels | Excerpts | Share of the 155 excerpts |
|---|---|---|
| At least one reviewer selected both | 98 | 63.2% |
| Labels came only from different reviewers | 57 | 36.8% |
Give the next reviewer the observation behind the label
For a business, a handoff may move from the person watching comments to the person responsible for the account. For a creator, it may move from an assistant to the creator. The next person needs to understand what was noticed before deciding whether to reply, seek more context or apply the account’s existing policy.
Keep each person’s selections together. If a reviewer selects both options, retain that pair as their assessment. If two reviewers choose different options, preserve the separate responses. A case can hold more than one reading without turning them into an assessment nobody actually made.
Then add a short explanation of the relevant passage. In your own workflow, identify what appears to be quoted, who seems to be addressed & which surrounding reply helps explain the exchange. Leave uncertainty visible when the available context does not answer the question. These are practical suggestions; the dataset did not test their effect on decisions.
A short note can be enough. The aim is to let the next person follow the first person’s reasoning without rebuilding the whole review. For a team passing cases between shifts or between a brand & a creator, that means handing over the original observation as well as the category attached to it.
A fictional example with identical label totals
Consider two invented review panels, each with 10 people assessing one fictional excerpt. The panels illustrate the arithmetic; they are not actual people, quotations or cases from the dataset. Both summaries show one quotation/reporting selection & one recipient-directed selection.[8]
In the first panel, Reviewer A selects both options. The other 9 people select neither of these two options. There is one person whose response contains the pair. A handoff can accurately preserve that person’s combined assessment while leaving the final action for a separate decision.
In the second panel, Reviewer A selects quotation/reporting & Reviewer B selects recipient-directed attack. The remaining 8 select neither option. The field totals still read one & one, but no person selected both. Calling this one person’s combined assessment would add a relationship that the individual responses do not contain.
The example also explains why we counted excerpts rather than adding every matching person. If two people in the first panel had each chosen both labels, the excerpt would still enter the same-reviewer group once. Its classification asks whether such a pair existed, not how many people supplied one.
For the second panel, a short fictional handoff could read: “Decision still open. Reviewer A identified quotation/reporting; Reviewer B identified language directed at the recipient. Keep both notes with the excerpt & its earlier reply. The account owner will check which passage each reviewer meant before choosing the action.” The note passes on an unresolved question without rewriting two people’s responses as one person’s conclusion.
In a real handoff, keep the two separate notes from the second panel. The next reviewer can read them alongside the text, ask what each person meant & make the account’s policy decision. The study does not establish whether either reviewer was right or which action that fictional case should receive.
The same label totals can come from different review patterns
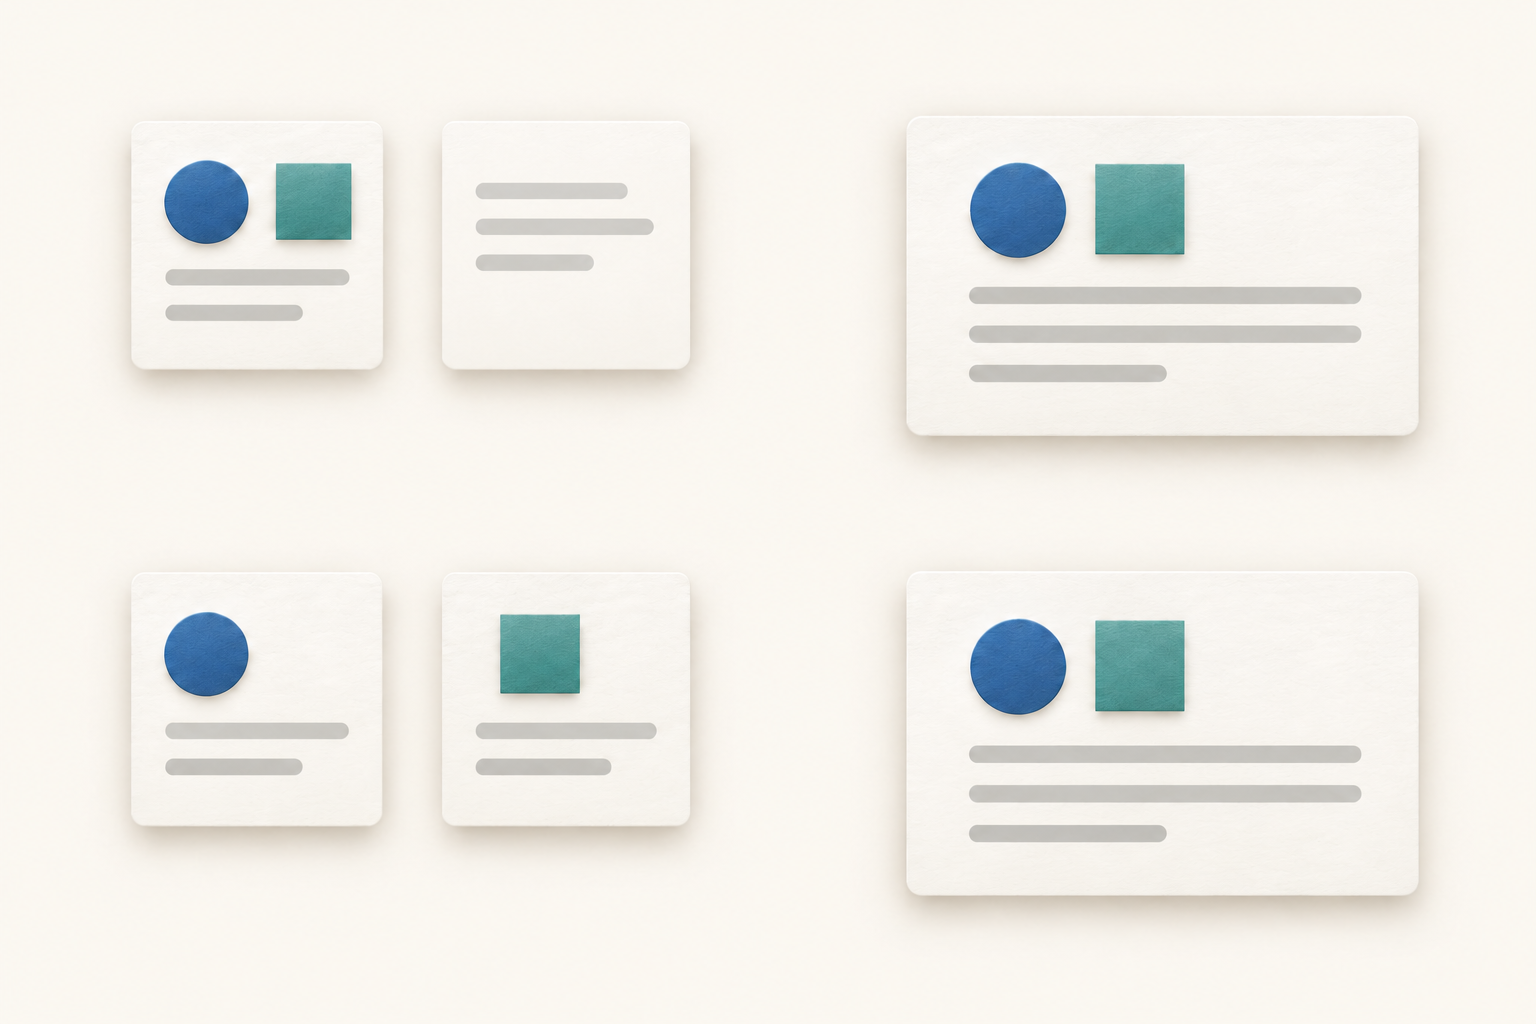
One reviewer selects both
The first invented panel has one person choosing both labels & 9 choosing neither of these two options.
Two reviewers select one each
The second has one person choosing quotation/reporting & another choosing recipient-directed attack. The other 8 choose neither option.
Keep the policy decision separate from the description
A description of what appears in a comment & a decision about what to do with it serve different purposes. A reviewer may notice quoted language while the account owner still needs to consider the surrounding exchange & the applicable policy. Preserve those steps separately so a later reader can see how the decision was reached.
For a business working with a creator, agree who makes that decision before a difficult exchange arrives. The person who understands a product complaint may not be the person authorized to change an account’s moderation approach. A clear handoff can name both roles without assuming that every case needs several reviewers.
For a creator working alone, the same distinction can live in one note: what you noticed, what context you checked & what you decided. One person can perform several steps while keeping their purposes clear. The dataset does not show that adding staff or another review layer improves outcomes.
Keep separate observations separate until you understand their relationship. Different selections may reflect different areas of focus rather than contradictory accounts. A quotation/reporting selection is not an automatic exemption, & a recipient-directed selection is not a measured recommendation to delete. The useful next action is the one supported by the actual exchange & the account’s rules, rather than an action inferred from our archive percentages.
A comment-review worksheet you can copy
Copy these fields into your existing review document or handoff. Use only the information your team needs, with access appropriate to the conversation. The worksheet is available here without a sign-up; it is practical guidance rather than an observed process from the study.[8]
Case: [Link or internal reference.] Account/channel: [Where the exchange appears.] Time checked: [Date & time.] Keep the reference stable so the next person can find the same material.
Purpose: [What question needs a decision?] Owner: [Who will decide?] Next person: [Who needs the handoff, if anyone?]
Presented text: [The passage being reviewed, retained in your approved workspace.] Surrounding context: [Relevant earlier or later replies.] Missing context: [What could not be checked.]
Reviewer: [Name or internal reviewer reference.] Assessment time: [Date & time.] Keep each person’s entry separate, even when several people use the same labels.
Quotation/reporting observation: [Yes, no or unclear.] Basis: [Which passage appears to quote or report another person’s attack?] Do not use this field as a harmlessness decision.
Recipient-directed observation: [Yes, no or unclear.] Basis: [Which passage appears directed at the recipient, & why?] Keep this answer independent of the quotation/reporting observation.
Other relevant observations: [Any other issue the account’s policy needs considered.] Do not treat the absence of one of the two study labels as a complete account of the exchange.
Relationship between reviews: [One person selected both, different people selected different options, or unclear.] If reviewers differ, preserve their individual notes before summarizing the case.
Policy reference: [The applicable rule or guidance.] Decision: [The action actually chosen, or the unresolved question.] Reason: [How the observation & context support that decision.]
Follow-up: [Who does what next, if anything?] Handoff time: [When it moves to that person.] Outcome: [What happened after the decision, if checked.] Do not mark an intended action as completed.
Review again when: [A specific event or missing piece of context, if another look is needed.] The worksheet does not require repeated review of every case; use a reason that fits the situation.
The year check kept the same 155 excerpts
We specified two supporting checks before calculating the label pairings. The first omitted excerpts dated 2016 because the released files’ year range extended beyond the periods described in the source overview & original paper. That left 13,809 eligible random-sample excerpts. The same 155 had both labels, with the same 98/57 split.[5]
The other check used the dataset’s separately sampled material from around blocking events. With the same exact-10-judgment rule, it contained 42,383 excerpts. Of the 2,457 with both labels somewhere, 1,354 had a same-reviewer pair & 1,103 had the labels supplied only by different people: 55.1% & 44.9% respectively.
The block-enriched group has a different sampling purpose, so we kept it separate. Its percentages do not replace the main result or become evidence about current brand comments. The year check addresses the recorded date range; neither check removes the need to interpret these as subjective judgments on selected historical excerpts.
How the two preselected checks compared
Every row uses exactly 10 complete judgments per excerpt. The block-enriched sample has a separate sampling purpose. Excluding 2016 addresses a difference between the released year range & source descriptions.
| Preselected comparison | Eligible excerpts | Excerpts with both labels anywhere | With a same-reviewer pair | Different-reviewer-only | Different-reviewer-only share of both-label excerpts |
|---|---|---|---|---|---|
| Random sample, exactly 10 judgments | 13,824 | 155 | 98 | 57 | 36.8% |
| Block-enriched sample, kept separate | 42,383 | 2,457 | 1,354 | 1,103 | 44.9% |
| Random sample excluding 2016 | 13,809 | 155 | 98 | 57 | 36.8% |
How we traced the labels back to individual judgments
We used version 6 of Wikipedia Talk Labels: Personal Attacks, a public dataset from the Wikipedia Detox project. The released files contain text derived from historical discussion-page revisions & multiple crowd-worker judgments for each excerpt. This analysis used the individual responses; it did not create new judgments or evaluate a moderation system.[1][2]
Our main comparison started with the release’s random-sample group & retained excerpts with exactly 10 distinct, complete judgments. Holding the number at 10 gave each excerpt the same number of opportunities to receive a paired selection. It also selected 13,824 of the 37,492 released random-sample excerpts, so the result does not describe that entire group.[3]
Each selected excerpt contributed one count. We checked whether either label appeared anywhere, then whether both appeared in a single person’s response to that same excerpt. The five categories are mutually exclusive & sum to 13,824. The 155-excerpt denominator comes from the two categories with both labels, rather than from all judgments or all source excerpts.[4]
Before looking at pairings, we fixed the sampling groups, coverage rule, year check & a minimum of 100 excerpts in the main conditional comparison. The observed 155 met that requirement. We did not set a required percentage, change the rule to favor a result or pool the block-enriched material with the random group.
The original research already used individual judgments, & later work aggregated each attack field by majority. Our narrower contribution is this descriptive comparison of who supplied the two options within a fixed set of judgments. It is not a correction to those studies’ methods. The download provides aggregate results, methods & reproduction instructions using the separately available public source files.[6][7]
Make the next review easier to follow
The useful question for a social media moderation handoff is who made each observation & what they were describing. In this selected archive comparison, 57 of 155 excerpts with both labels had no individual reviewer who selected the pair. That relationship would be lost in a summary containing only the two label names.
Keep the person’s observations, the relevant context & the final decision connected. A business or creator can then explain what the case contains & why the chosen action follows, without asking a category label to do the work of the whole review.
No sign-up required. The package includes anonymous aggregate results, methods, reproduction instructions & the reusable worksheet. It contains no original discussion text, revision IDs, worker IDs or demographics. The original public source files are available separately from the linked release.
Sources & notes
- Source: Wikipedia Talk Labels: Personal Attacks, Figshare version 6, DOI 10.6084/m9.figshare.4054689.v6, released February 2017 under CC0. We used attack_annotated_comments.tsv (file 7554634) & attack_annotations.tsv (file 7554637), with producer MD5 & independently computed SHA-256 checks. Influence IQ completed the selection, calculations & interpretation on October 25, 2026 (UTC). The study did not collect new comments, create new annotations or measure a live social platform.
- The producer defines quoting_attack as a worker’s perception of quoting/reporting an attack from another comment, & recipient_attack as an attack directed at the recipient. The interface allowed multiple choices. General attack is a separate source response, not an OR reconstructed from subtypes in this analysis. The released text concatenates additions made during a revision; it is not an edit summary, necessarily one whole post or a complete conversation. Discussion namespaces, sampling groups & model train/dev/test splits retain their documented meanings.
- The complete files contained 115,864 unique excerpts, 1,365,217 unique revision/worker judgment pairs & 4,053 workers. Structural qualification found no duplicate pairs, orphan joins, malformed rows or missing/invalid flag values. Eligibility required exactly 10 distinct complete judgments across all 5 source flags, both documented discussion namespaces & all model splits, with one equal-weight count per excerpt. The primary random group retained 13,824 of 37,492 excerpts. The separately selected block-enriched group retained 42,383 of 78,372. Repeated workers across different excerpts were legitimate; no identical-text merging, crossflag-coherence deletion or general-attack recoding was imposed.
- Let Q indicate any quotation/reporting selection & R any recipient-directed selection for an eligible excerpt. Both-any presence requires at least one Q & one R somewhere among the 10 judgments. Same-reviewer presence additionally requires Q & R in one revision/worker response; different-reviewer-only presence has no such response. The primary conditional denominator is 98 + 57 = 155; exact fractions 98/155 & 57/155 are displayed as 63.2% & 36.8%. Percentages use exact rational arithmetic & half-up rounding to 1 decimal. Before calculating the pairings, we required at least 100 excerpts with both labels for the main conditional comparison, with no favorable percentage threshold. No population confidence interval, significance test, independence claim or accuracy estimate was made.
- The predeclared block-enriched sensitivity used the same exact-10-judgment rule, kept separate from the random primary. Its five counts were 20,911 neither label, 959 quotation/reporting without recipient-directed, 18,056 recipient-directed without quotation/reporting, 1,354 same-reviewer both & 1,103 different-reviewer-only both; total 42,383, conditional denominator 2,457. Excluding 2016 from the random primary left 13,809 excerpts, with five counts 12,012 / 406 / 1,236 / 98 / 57 in that same order. Its 155 conditional excerpts & 98/57 pairing split were unchanged. These are descriptive checks, not independent population replications or evidence that the sampling groups are comparable.
- Wulczyn, Thain & Dixon’s 2017 Ex Machina: Personal Attacks Seen at Scale established the underlying crowdsourcing & modeling work. Cécillon & colleagues’ 2020 WAC paper retained a worker-by-field matrix & aggregated the attack fields separately by majority. Those are existing methods, not errors established by this study. Our comparison uses any-of-10 label presence & same-response pairing, not majority-label performance. Influence IQ’s comparison counts whether the two options were supplied by the same reviewer or only by different reviewers within each selected excerpt.
- The source overview describes 2001–2015 & the original paper 2004–2015; the pinned version 6 files contain year values 2001–2016. The producer’s logged-in schema says 0/1, while the released file uses False/True; binary flag strings are 0.0/1.0. We preserved these documented/observed differences without assigning a cause. The parser accepts the exact released literals, without rounding or coercing label values. The package documents source versions, selection rules & the steps for reproducing the analysis from the public files.
- The two 10-person review panels, Reviewer A/B responses & handoff choices are fictional teaching examples. They contain no original discussion text or identifiers from the dataset. Both invented panels have one quotation/reporting selection & one recipient-directed selection, but only the first has a same-person pair. The worksheet & conceptual illustrations are practical explanations, not observed source workflows, tested moderation policies or guarantees of better decisions.
All language versions are translated directly from the English source. Every edition describes the same historical English Wikipedia dataset & selected judgments. Translation does not create local-market findings. Influence IQ is responsible for the analysis, interpretation & translations.